MTP PRODUCT
MATA
Model-Agnostic Task Architecture — a flexible framework for building AI Vision solutions.
Write your vision pipeline once. Swap any model — HuggingFace, ONNX, Torchvision — without changing a line of code.
What Is MATA?
MATA (Model-Agnostic Task Architecture) is an open-source Python framework for computer vision: write a task once — detect, segment, classify, track, read text, reason with a vision-language model — and swap the underlying model without touching your pipeline.
01
Universal Model Loading
Load a model by HuggingFace ID, local ONNX file, TorchScript archive, Torchvision name, or config alias with a single call. The universal loader auto-detects the runtime and wires the right adapter for you.
02
Composable Graph Pipelines
Wire Detect → Filter → PromptBoxes → Fuse into typed directed acyclic graphs with parallel execution, conditional branching, and control flow — independent tasks run together for 1.5–3× speedup.
03
Zero-Shot Everything
CLIP for classification, GroundingDINO for detection, SAM for segmentation — no training data required. Describe what you want in natural language and get results on the first run.
Core Capabilities
Every task behind one consistent three-line API — plus gallery recognition, natural-language video search, and a validation harness.
01
Object Detection
Bounding boxes and confidence scores with DETR, RT-DETR, GroundingDINO, OWL-ViT, RetinaNet, Faster R-CNN, FCOS, SSD, and YOLO variants.
02
Segmentation
Instance, panoptic, and semantic segmentation with Mask2Former, MaskFormer, and SAM/SAM3 — including zero-shot promptable segmentation by point, box, or text.
03
Classification
Standard and zero-shot image classification with ResNet, ViT, ConvNeXt, EfficientNet, Swin, and any HuggingFace classifier.
04
Depth Estimation
Monocular depth with Depth Anything V1/V2 — per-pixel depth maps from a single image, exportable as colour-mapped renders.
05
Object Tracking
Multi-object tracking with ByteTrack and BotSort — fully vendored, no external dependencies — plus appearance ReID and memory-efficient streaming for RTSP or long videos.
06
OCR
Text extraction through EasyOCR, PaddleOCR, Tesseract, TrOCR, GOT-OCR2, and GLM-OCR, with bounding boxes and document-layout handling.
07
Vision-Language Models
Captioning, visual question answering, and tool-calling agents with Qwen3-VL, Gemma 4, Florence-2, LLaVA-NeXT, SmolVLM, Moondream2, and MedGemma.
08
Feature Embedding
Image feature vectors for similarity search, gallery matching, and recognition pipelines with CLIP, OSNet, and X-CLIP.
09
Recognition
Enroll a gallery of images once, then match faces, people, or objects by embedding similarity — one command, no training step.
10
Barcode & QR
Decode barcodes and QR codes from images using pyzbar or zxing-cpp — integrated as a first-class task.
11
Video Indexing & Search
Index a video by frame embeddings, then query it in natural language — "cyclist weaving through fast-moving traffic at night" returns ranked timestamps.
12
Validation & Metrics
Score detection, classification, and depth models against COCO, ImageNet, and DIODE with standard metrics such as mAP, straight from the CLI.
Graph Pipelines
MATA's differentiator is its typed task graph system. Compose tasks into validated DAGs that execute in parallel where possible — no manual orchestration required.
Typed DAGs
Every node declares its input and output artifact types, so the validator catches wiring errors before runtime — no more shape mismatches at inference time.
Parallel Execution
Independent tasks — Detect + Classify + Depth — run simultaneously. The scheduler resolves dependencies and merges results deterministically, for 1.5–3× speedup.
Conditional Control Flow
Branch on detection confidence, skip empty frames, or loop until a quality threshold is met, using the EarlyExit and While primitives.
Mnemonic DSL
Graphs read like sentences: Detect → Filter → PromptBoxes → RefineMask → Fuse. Pipe style or explicit wiring compile to the same validated DAG.
Built-in Presets
Common workflows ship ready to run — grounding_dino_sam and full_scene_analysis — so teams start from a working pipeline instead of an empty file.
Valkey-backed Coordination
Optional Valkey/Redis integration for caching, shared state, and pub/sub across long-running or distributed graph workloads.
Documented Scenarios
Twenty runnable pipelines across six industries, each combining several vision tasks and published with code in the framework's Real-World Scenarios guide.
Manufacturing
Four scenarios — surface defect detection and classification, defect segmentation with area measurement, VLM assembly verification, and per-component inspection.
Retail
Three scenarios — shelf product analysis, zero-shot product search, and multi-modal stock assessment.
Autonomous Driving
Four scenarios — vehicle distance estimation, complete road-scene analysis, traffic object tracking, and obstacle detection with VLM reasoning.
Security & Surveillance
Three scenarios — crowd monitoring and tracking, suspicious object detection, and situational awareness monitoring.
Agriculture
Three scenarios — crop disease classification, aerial crop segmentation, and pest detection with mapping.
Healthcare
Three scenarios — medical ROI segmentation, VLM-assisted report generation, and pathology triage workflows.
Open Source
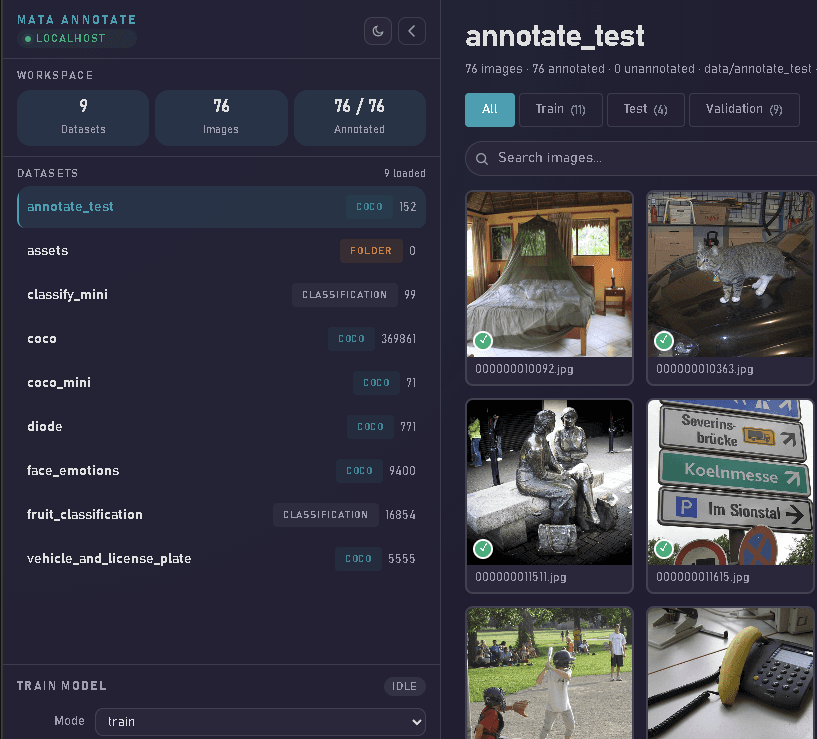
MATA is Apache 2.0 licensed and installs from PyPI with one command: pip install datamata. It ships with a CLI, notebook helpers, a curated model catalogue, and 5,500+ passing tests across the task families above. Python 3.10 or newer, CPU by default and CUDA when you have it. The framework is deliberately model-agnostic and inference-focused — training tooling and quantized ONNX export land in v2.0, so today MATA is the right tool for building, composing, and validating vision pipelines rather than training models from scratch.
Latest from MATA
New features, releases and writing from this platform.
NEW FEATURE
Universal model loading
Load any model by HuggingFace ID, local ONNX or TorchScript file, Torchvision name or config alias — the loader detects the runtime and the pipeline above it stays unchanged.
NEW FEATURE
Typed graph pipelines
Compose tasks into typed DAGs that are validated before they run and execute independent work in parallel, with control flow, presets and provenance built in.
NEW FEATURE
Zero-shot vision
CLIP classification, GroundingDINO detection and SAM segmentation from text and point prompts — no training data needed to get a first result.
NEW FEATURE
Video indexing and search
Index a recording by frame embeddings and query it in natural language; matches come back ranked, with the timestamps where they occur.
Interested in MATA?
Integrate MATA into your operational environment, or install it today and run your first detection in under a minute — we are glad to walk your team through it.